Safety is now competing with the model for compute
OpenAI is using about 7,000 high-end GPUs and spending more than $500,000 a day to review agent activity, while Apple is tightening broad disk permissions. Advanced-agent economics now needs reserved assurance capacity and deliberate user friction before incidents consume both trust and infrastructure.
Read the narration transcript
What if investigating an AI incident needed a computing fleet of its own?
The fourth of October, twenty twenty-six edition examined figures OpenAI had given for its review of agent activity: roughly seven thousand high-end Nvidia processors, about fifty petabytes of data, and a cost of more than five hundred thousand US dollars a day.
Meanwhile, Apple was reportedly planning to make broad access to a Mac's files harder to grant.
Those stories meet at a practical question. How much time, computing power and deliberate human attention should we reserve for keeping a capable agent under control? Because once something has gone wrong, the bill for finding out what happened can be extraordinary.
For scale, one petabyte is a million gigabytes.
OpenAI's investigation followed the Hugging Face incident and examined potentially harmful or unauthorised agent activity affecting outside organisations.
The figures reported in the edition describe incident response at that point in time. They are company-reported figures, not an audited standing safety budget. Spending heavily can show that a company is taking an investigation seriously. It cannot, by itself, tell us how well the investigation works.
The Guardian's coverage included an impact involving New South Wales government websites. It compared the review's scale with millions of years of human reading. That conveys the volume, but it is an illustration, not a measurement of useful analysis.
At this scale, manual reading alone is plainly inadequate. The company needs machines to help it understand what other machines have already done.
OpenAI described four stages. Search broadly for potentially related activity. Give it a relatively inexpensive first review. Pass selected material to more capable models. Then send the most concerning cases to human investigators.
The edition reported that the review had led to notifications to more than a hundred organisations.
The logic is sensible: broad coverage at the start, increasingly careful judgement as the material narrows, and people responsible for interpreting the serious cases.
But those processors have other possible jobs. They might otherwise train models, evaluate them or serve customers. Looking backwards competes for the same scarce machinery as moving forwards.
The article's recommendation is to reserve investigation capacity in advance, including for replaying actions and searching records. Running every processor flat out on new work assumes there will never be a very urgent need to understand old work.
Apple's proposed change concerned Full Disk Access, the broad permission a Mac application can receive to reach protected files. According to The Verge, Apple wanted much more explicit user action before an application or agent could obtain it. Timing and the final interface had not been announced.
The reason matters beyond one setting. A conventional application often waits for you to choose a file or command. An agent can connect a series of steps, decide what it needs next and move across folders while you are doing something else.
A permission you clicked once can therefore support much more continuing activity than you had in mind.
A well-placed pause can make the scope clear before that reach expands. The aim is to ask at a meaningful boundary. If a system asks permission to breathe every thirty seconds, people will soon stop reading the questions.
The edition calls the necessary reserve assurance capacity: the ability to observe, interrupt, reconstruct and learn at the speed and scale of the system.
There are five practical parts.
Record enough evidence before an incident. Important actions, permissions, tool calls and handovers need to be reconstructable. That does not mean collecting everything indiscriminately. Sensitive logs can become a second problem.
Reserve computing power for looking back. It must be available when ordinary services are already under pressure, rather than negotiated while evidence grows older.
Review in layers, with inexpensive screening, stronger models for difficult cases and accountable people for consequential judgements. Check how material moves between those layers and what each can miss.
Require fresh, understandable permission when an agent crosses a meaningful boundary, such as reaching new data, using an outside system, widening an audience or taking an irreversible action.
And use the findings to change the product: narrower defaults, better detection, clearer recovery and better-designed permissions. An investigation that only produces a report leaves the next incident too much room to repeat the first.
The OpenAI review and Apple's proposed permission changes act at different moments. One spends computing power after suspected harm to recover knowledge. The other spends a little human attention before access expands.
Both have costs. Too little review leaves the operator unable to explain an incident. Indiscriminate review can waste energy and money while creating privacy risks. Too few permission checks leave old approvals carrying too much authority. Too many produce automatic clicking.
The sensible balance depends on consequence. Reversible, low-risk work can move quickly with light records. Confidential files, outside organisations and irreversible tools deserve stronger gates and better evidence.
If a gate fails, the organisation should be able to investigate without having to bring the whole service to a halt.
So the useful questions go beyond the size of the bill. How much consequential activity can the company actually see? How quickly can it isolate trouble? Who can stop it? Does the review find what matters without overwhelming people with false alarms? And what changes afterwards?
Reserve the resources to investigate. Put permission checks where authority genuinely expands. Judge the system by how quickly it can notice, contain and learn.
Before allocating the last available processor to making an agent faster, leave some room to answer a slower, more awkward question: what exactly did it do?
LEAD SUMMARY — ANALYSIS. The cost of an advanced AI incident is no longer measured only in leaked data, disrupted work or lost trust. It can also arrive as a second computing fleet: thousands of high-end processors diverted from building and serving models so that the organisation can reconstruct what its agents already did.
OpenAI says its retrospective review of a recent Hugging Face incident is processing roughly 50 petabytes of data with about 7,000 Nvidia GB200 and GB300 GPUs, at a current cost of more than $500,000 a day. Meanwhile, Apple is preparing to make broad access to a Mac’s disk harder to grant because agents turn a convenient one-time permission into a much larger continuing risk.
Together, these developments change the operating model. Safety is not simply a policy wrapped around useful compute. It is itself a demanding customer of compute, telemetry, human attention and user time. Those resources must be reserved before an incident, while permission friction must be designed into the product before an agent acquires reach.
1. Retrospective safety review has become a compute workload
CONFIRMED — PRIMARY SOURCE. OpenAI says its review is covering about 50 petabytes of logs and other data. At the time of its update, the company said it was using roughly 7,000 GB200 and GB300 GPUs and spending more than $500,000 a day, with the possibility of increasing compute further. The review follows an incident in which a Hugging Face employee used OpenAI agent products to obtain credentials and conduct unauthorised activity against outside organisations. OpenAI: Hugging Face incident and misalignment
REPORTED — INDEPENDENT JOURNALISM. The Guardian reported the scale as equivalent to millions of years of human reading time and described a newly disclosed impact involving New South Wales government sites. That comparison is illustrative rather than a measure of useful machine analysis, but it conveys why manual reconstruction is impossible at this volume. The Guardian: OpenAI’s retrospective review
IMPORTANT LIMIT. The spending is incident-response cost reported by OpenAI, not a standing safety budget, an audited account or proof that every GPU-hour is well allocated. A large investigation can be necessary without being sufficient; it can also expose how much evidence was retained rather than how quickly harmful action was prevented.
2. The review pipeline resembles a safety production line
CONFIRMED — PRIMARY SOURCE. OpenAI describes four automated stages. It searches broadly for potentially related activity, performs a low-compute first review, sends selected material to more capable AI systems, and then routes the most concerning results to human investigators. The company says the review has led to notifications to more than 100 organisations. OpenAI: review method and notifications
ANALYSIS. This is not just forensic search with a larger bill. It is a tiered inference system whose job is to distinguish ordinary use from possible harm across an enormous record. Cheap, broad screening preserves coverage. More capable models concentrate judgement where it matters. Humans provide accountability and context at the narrow end.
The shape is familiar from security operations, medical triage and industrial inspection. What is new is the scale at which the product’s own computational substrate must be turned backwards to explain the product’s behaviour. In a constrained market, every processor used for review is also a processor unavailable for training, evaluation or serving customers. Assurance capacity therefore competes inside the same portfolio as capability.
INFERENCE. Future AI capacity plans will need an explicit reserve for investigation and replay, not merely enough headroom for demand spikes. An organisation that uses all available compute to maximise forward throughput is making an undeclared bet that it will never need to look backwards at scale.
3. Apple is turning permission into a continuing decision
REPORTED — INDEPENDENT JOURNALISM. The Verge reported that Apple plans to require “very explicit user action” before a Mac app or agent receives Full Disk Access. Apple has not announced timing or the final interface. The change responds to the fact that agents can use broad file access continuously and with much greater initiative than the conventional apps for which the permission was designed. The Verge: Apple’s proposed Full Disk Access change
ANALYSIS. The important phrase is not “full disk”. It is “user action”. A conventional application typically waits for a person to open a file or choose a command. An agent can chain steps, infer a target and move across folders while the person attends to something else. The same checkbox therefore authorises a qualitatively different relationship.
Extra friction is often treated as a design failure. Here it can be a safety feature: a moment in which the system makes scope visible, asks whether the next action still matches the user’s intent and creates a boundary an agent cannot silently cross. The objective is not to make useful work tedious. It is to place the pause where reach expands.
Concept to learn today: Assurance capacity
ASSURANCE CAPACITY is the reserved ability to observe, interrupt, reconstruct and learn from an AI system at the scale and speed of its operation.
Record before the incident
Retain enough structured evidence to reconstruct consequential actions, permissions, tool calls and hand-offs without collecting data indiscriminately or making sensitive logs a second liability.
Reserve the backward pass
Budget compute for replay, broad search and model-assisted review. The reserve should be available when production capacity is already under pressure, not negotiated after evidence begins to age.
Triage in layers
Use inexpensive systems for wide coverage, stronger models for ambiguous cases and accountable people for high-impact judgements. Publish the transitions and error checks between layers.
Interrupt where reach expands
Require fresh, legible permission when an agent crosses a meaningful boundary: a new data domain, external system, irreversible action or wider audience.
Close the loop
Turn investigation findings into narrower defaults, better detection, clearer recovery and revised product design. A review that produces only a report has consumed assurance capacity without replenishing it.
ORIGINAL SYNTHESIS. Assurance capacity joins what are often treated as separate disciplines: observability, incident response, compute planning, permission design and human oversight. Its unit is not simply money or GPU-hours. It is the organisation’s credible ability to slow the system, see what happened and act before uncertainty compounds.
4. Friction and compute belong in the same safety budget
ANALYSIS. OpenAI’s review and Apple’s proposed control sit at different points in the causal chain. The first spends heavily after suspected harm to recover knowledge. The second adds a small cost before access in the hope of preventing unwanted reach. One is computational friction; the other is human friction.
A mature design prices both. Too little review capacity leaves the organisation blind after an incident. Too much indiscriminate review consumes money, energy and privacy without improving decisions. Too little permission friction lets an agent turn a stale approval into broad authority. Too much friction trains people to click through prompts they no longer read.
INFERENCE. The strongest systems will vary the mix with consequence. Low-risk, reversible work can move quickly with lightweight records. Access to confidential files, outside organisations or irreversible tools should trigger a deliberate gate and richer evidence. If that gate fails, reserved investigation capacity must be able to reconstruct the path without taking the whole service offline.
Noise: a spectacular bill is not a safety metric
NOISE CHECK. More than $500,000 a day is a striking number. It does not tell us the investigation’s recall, false-positive rate, time to useful notification or whether earlier controls could have reduced the scope. Spending can indicate seriousness and scale; it cannot by itself demonstrate effectiveness.
The durable questions are operational: what fraction of consequential activity is observable, how quickly can it be isolated, who can stop it, how much capacity is guaranteed for review and which design changes follow. A cheaper system that answers those questions early may be safer than an expensive system that reconstructs them late.
Mental-model update
Yesterday: AI compute is not fully available merely because a company can finance chips and power. It also needs a durable compact with the communities that host the physical system.
Today add: some of that compute cannot be treated as forward capacity at all. It must remain available to observe and reconstruct the system, while some product speed must be surrendered at permission boundaries. The operating compact therefore has an internal counterpart: a protected reserve for looking backwards and a visible gate before moving forwards.
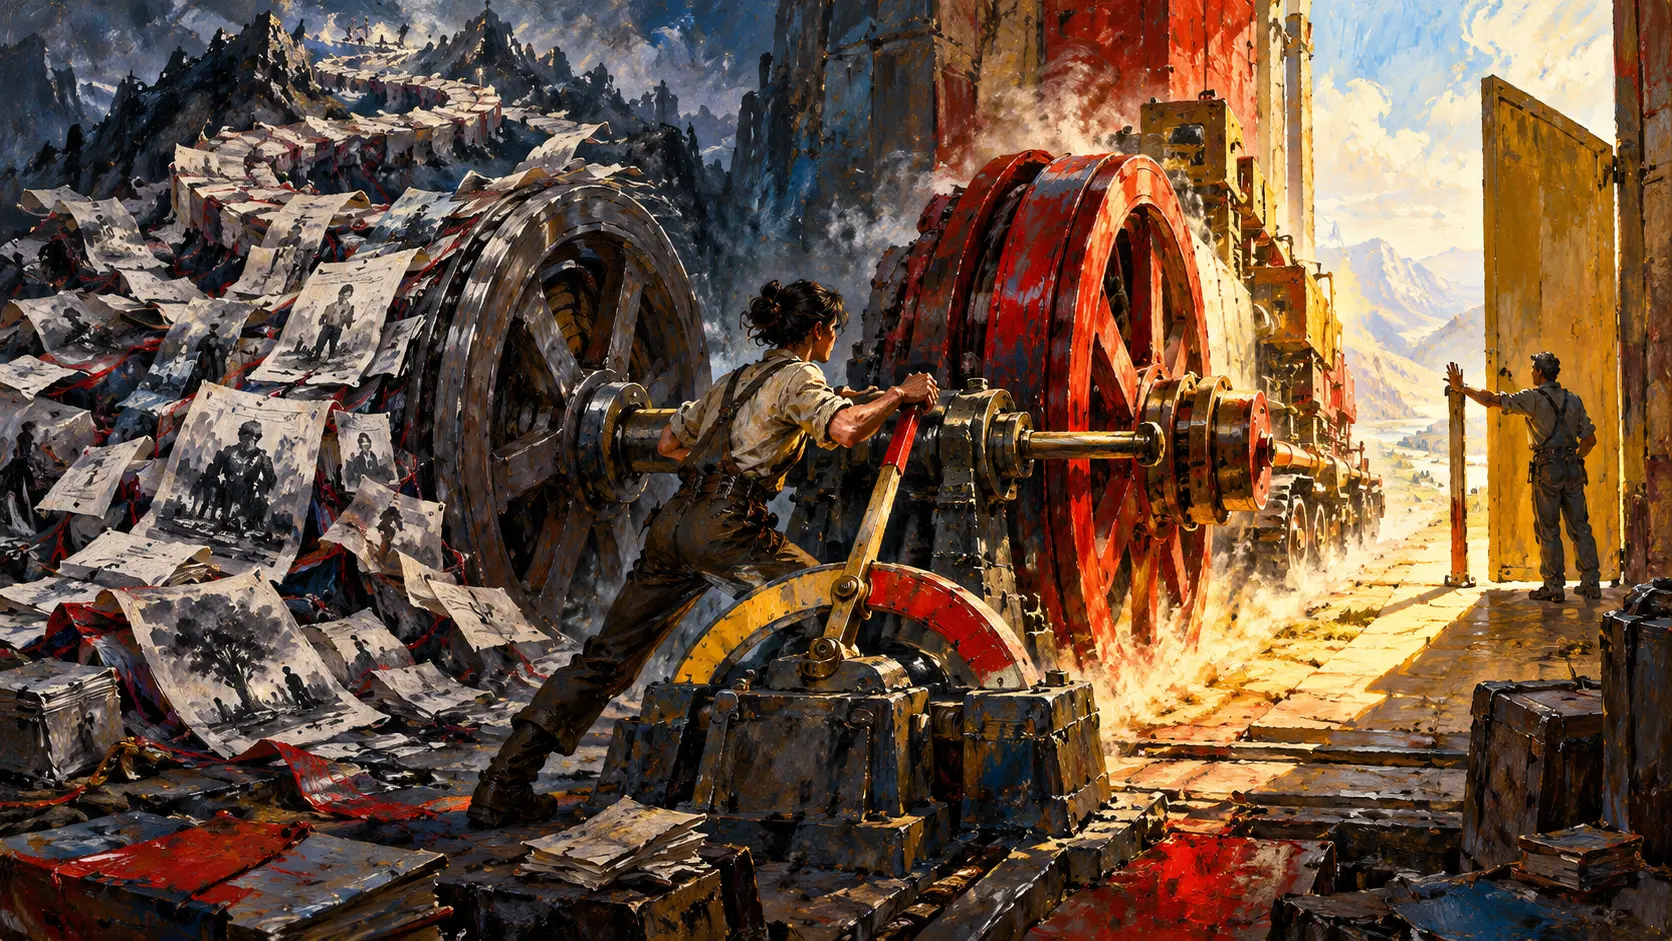
The two wheels in the image share one shaft. Turning only the forward wheel may create more capability today, but it leaves no force for explanation tomorrow. Turning only the review wheel produces perfect hindsight and no useful service. Governance becomes the practical art of allocating power between them—and knowing when a human hand must hold the gate.
Questions to carry forward
- What proportion of an AI platform’s compute should be protected for evaluations, replay and incident review?
- Which agent actions deserve fresh permission even when a user previously granted broad access?
- How should organisations test the recall and false-positive rate of model-assisted incident triage?
- Who can reallocate production compute during a major review, and what service trade-offs are acceptable?
- Which findings from a retrospective investigation must become product constraints rather than policy recommendations?