AI governance has moved from rules to capability
Meta has released persistent frontier agents while the UK resumes pre-release testing, extends AI cyber hardening after identifying 1,352 vulnerabilities and builds an agent-incident response function. The emerging requirement is a public capability stack: visibility, defensive use, incident command and independent verification.
AI-generated voice. Short companion, not a full reading.
Read the narration transcript
Rules matter. But who can test the systems those rules are supposed to govern?
That is the question running through AyEye Today for the thirteenth of October, twenty twenty-six: AI governance has moved from rules to capability.
The article brings together two developments. Meta describes its new Muse Wonder models as persistent agents, able to carry context across conversations and keep working through obstacles. Those are supplier claims. The article cautions that benchmark comparisons are largely vendor-reported and the full safety evidence is still developing.
Meanwhile, a UK parliamentary statement says the AI Security Institute is again evaluating leading models before release. It also reports that frontier AI pilots found and helped address thirteen hundred and fifty-two vulnerabilities across five hundred and forty-eight government code repositories. A specialist capability for serious agent incidents is being developed.
The connection is the article's own analysis. Public assurance needs operational strength of its own. It calls this the public capability stack: pre-release visibility, defensive application, incident command and independent verification.
Access lets evaluators test systems before release. Defensive use teaches institutions how the technology behaves in practice. Incident command helps contain consequences and preserve evidence when something goes wrong. Verification lets important claims be challenged throughout a system's life.
There is a tension. Government may depend on the same suppliers it needs to scrutinise. The article argues for clear boundaries between procurement, testing and enforcement, with visible dependencies and credible exit plans.
None of the announcements proves that this stack is complete. Proposed reporting changes are not enacted law. The vulnerability count does not tell us severity or how much repair is finished. A one-off test cannot cover every later combination of memory, tools and intent.
The practical question is whether public institutions can inspect, defend and respond at something approaching the speed of the systems they govern.
Read the full article for the evidence, qualifications and questions to carry forward. This is a short companion briefing, voiced synthetically for LecXie. Chiappe and OpenAI.
LEAD SUMMARY — ANALYSIS. Regulation is fond of nouns: a bill, a standard, a regulator, a reporting duty. The latest AI developments suggest the harder work is a verb. A public institution must be able to inspect, test, defend and respond at something approaching the speed of the systems it governs.
On 12 October, Meta released Muse Wonder and Muse Wonder Full, its most capable models to date, built for persistent personal and professional agent work. The company says the models can carry relevant information across conversations, keep working through blockers and operate in domains including law, finance and health. On the same day, the UK government disclosed that its AI Security Institute is again testing leading models before release, that frontier AI pilots have found and helped address 1,352 vulnerabilities across 548 government code repositories, and that it is building a specialist response capability for serious agent incidents.
These are not opposite stories about acceleration and restraint. Together they describe a new institutional contest: private AI capability is broadening, persisting and multiplying; public assurance must become a capability in its own right.
1. Meta has returned to the frontier with an agent, not merely a chatbot
CONFIRMED — PRIMARY SOURCE. Meta says Muse Wonder is available through its Model API and Muse Code, while the more capable Wonder Full is available to Muse Code subscribers. Both are intended for multi-step work such as navigating an insurance claim, understanding a lease or building an application.
The architectural emphasis matters more than the leaderboard headline. Meta describes two linked capabilities. “Active Memory” carries important personal context across conversations and retrieves it when relevant. “Active Focus” keeps the system working towards a goal, trying alternatives, recovering from errors and asking before important actions. The models are therefore being presented as persistent actors operating across time, context and tools.
REPORTED — INDEPENDENT JOURNALISM. The Financial Times reports that Mark Zuckerberg regards the release as Meta’s return to the AI frontier after a costly restructuring and infrastructure build-out. Meta claims advantages over OpenAI and Anthropic on some tests, but those comparisons remain substantially vendor-reported.
ANALYSIS. Another credible frontier supplier changes the governance problem even if its benchmark lead later proves narrow. The frontier is becoming a market of persistent agent systems rather than a small club of conversational models. Each supplier brings a different release surface, safety framework, business model and willingness to provide outside access. Oversight cannot depend on one laboratory’s vocabulary or goodwill.
2. The UK is beginning to build an operational counter-capability
CONFIRMED — OFFICIAL PARLIAMENTARY RECORD. In a written statement to Parliament, AI minister Kanishka Narayan confirmed that the UK AI Security Institute is conducting pre-release evaluations of the latest generation of models, including Google’s Gemini 4 Argon. He said the government had worked with laboratories and the US administration to retain that access.
The same statement reported a practical use of frontier capability rather than another committee. Two government pilots used AI to find and address 1,352 vulnerabilities across 548 code repositories in 18 departments. The programme is being extended urgently across government.
Narayan also announced the first steps towards a specialist government capability for major incidents involving agentic AI. Officials are considering changes to the Cyber Security and Resilience Bill covering near-miss reporting, AI-driven risks across organisations and how lessons from incidents should be shared.
ANALYSIS. This is a meaningful step beyond asking laboratories to behave well. The state is trying to acquire three abilities of its own: to see a model before release, to use advanced models defensively and to organise a response when an agent crosses its instructions. None is yet mature, but together they form the beginnings of an institutional counterweight.
Concept to learn today: the public capability stack
THE PUBLIC CAPABILITY STACK is the set of operational abilities a government or independent authority needs to govern frontier AI without becoming technically dependent on the companies it oversees.
Pre-release visibility
Independent evaluators need timely access, suitable compute and enough technical freedom to test claims before a system reaches millions of users. A briefing about the model is not equivalent to testing the model.
Defensive application
Public institutions need to use frontier systems against their own vulnerabilities. This creates practical knowledge of what the technology can and cannot do, rather than leaving government with a policy view assembled entirely from outside reports.
Incident command
When an agent acts beyond its instructions, somebody must be able to join logs across companies and affected organisations, contain consequences, preserve evidence, notify people and coordinate repair.
Independent verification
Important claims about safeguards, monitoring, privacy and model behaviour need evidence that can be reproduced or challenged. Verification is a continuing function, not a certificate issued once before launch.
ORIGINAL SYNTHESIS. Rules tell an institution what it is allowed to demand. Capability determines whether it can understand the answer. As AI systems gain memory, persistence and tool access, the credibility of governance will rest increasingly on whether public bodies can perform these four functions themselves.
3. Access is becoming a constitutional question for AI governance
The UK’s renewed pre-release testing is encouraging precisely because it had become uncertain. A safety institute that sees only the models a developer chooses to share cannot reliably distinguish independent oversight from voluntary consultation.
ANALYSIS. Stable access arrangements should not depend on a sequence of personal relationships between ministers, foreign administrations and laboratory executives. They need clear triggers: which models qualify, how much notice is required, what information accompanies access, which findings remain confidential and what happens when a developer refuses.
That does not necessarily require publishing model weights or sensitive exploit details. It requires an auditable right to inspect systems with sufficient depth and time. The more plural the frontier becomes, the less plausible it is to renegotiate that right separately for every model family and every political season.
4. Government must not become both dependent customer and indulgent auditor
The vulnerability pilots show the positive side of public capability. Frontier models can help a government inspect code at a scale that conventional teams struggle to reach. Finding 1,352 issues across hundreds of repositories is operationally useful, provided the findings are validated, prioritised and repaired.
INFERENCE. Success creates a new governance risk. If public cyber defence becomes dependent on the same laboratories whose models the government must scrutinise, access to a valuable service can soften the appetite for difficult oversight. Procurement, testing and enforcement functions therefore need institutional separation, even when they use the same underlying technology.
The goal is not artificial neutrality. Government will inevitably depend on private infrastructure, expertise and models. The safeguard is visible dependency: documented provider concentration, exit plans, reproducible evaluation methods, independent compute where proportionate and a clear line between partnership and permission.
5. Persistent agents require continuous rather than episodic supervision
Meta’s model description makes the timing problem concrete. Memory operates across conversations. Focus operates across failed attempts. The agent may return to information or pursue alternatives long after the initial instruction.
ANALYSIS. A one-off pre-release test cannot cover every later combination of memory, tools, data and user intent. Pre-release evaluation remains important, but it has to connect to post-release telemetry, near-miss reporting, external incident evidence and the power to change permissions or stop a deployment.
This is where the new UK strands fit together. Early access helps identify foreseeable risks. Defensive deployment teaches institutions how the capability behaves in their own environment. Incident response deals with the remainder. Verification connects claims across the lifecycle. The stack is useful because no single layer is being asked to prove safety by itself.
Noise: frontier claims and policy announcements are not finished systems
IMPORTANT LIMIT. Meta’s performance claims come principally from its own evaluation suite. The company says a fuller safety report will follow, so independent readers do not yet have the complete evidence behind its strongest safety assertions. “Frontier” is a competitive description, not a regulated grade.
The UK measures are also early. Pre-release access has resumed, but the parliamentary statement does not create a permanent statutory access right. The incident-response capability is being developed. Possible reporting changes are under consideration, not enacted law. The vulnerability count does not reveal severity, false positives or how much remediation is complete.
Those qualifications prevent a premature victory lap. They do not erase the direction of travel: another large platform is deploying persistent agent capabilities while a government is assembling the means to inspect, use and respond to them.
Mental-model update
Earlier: AI governance meant writing obligations for frontier laboratories and checking whether companies followed them.
Now add: governance is itself a technical and operational system. It needs access, compute, evaluators, defensive practice, incident command and verifiable evidence. A state that can issue rules but cannot test a model or reconstruct an incident is governing mainly on paper.
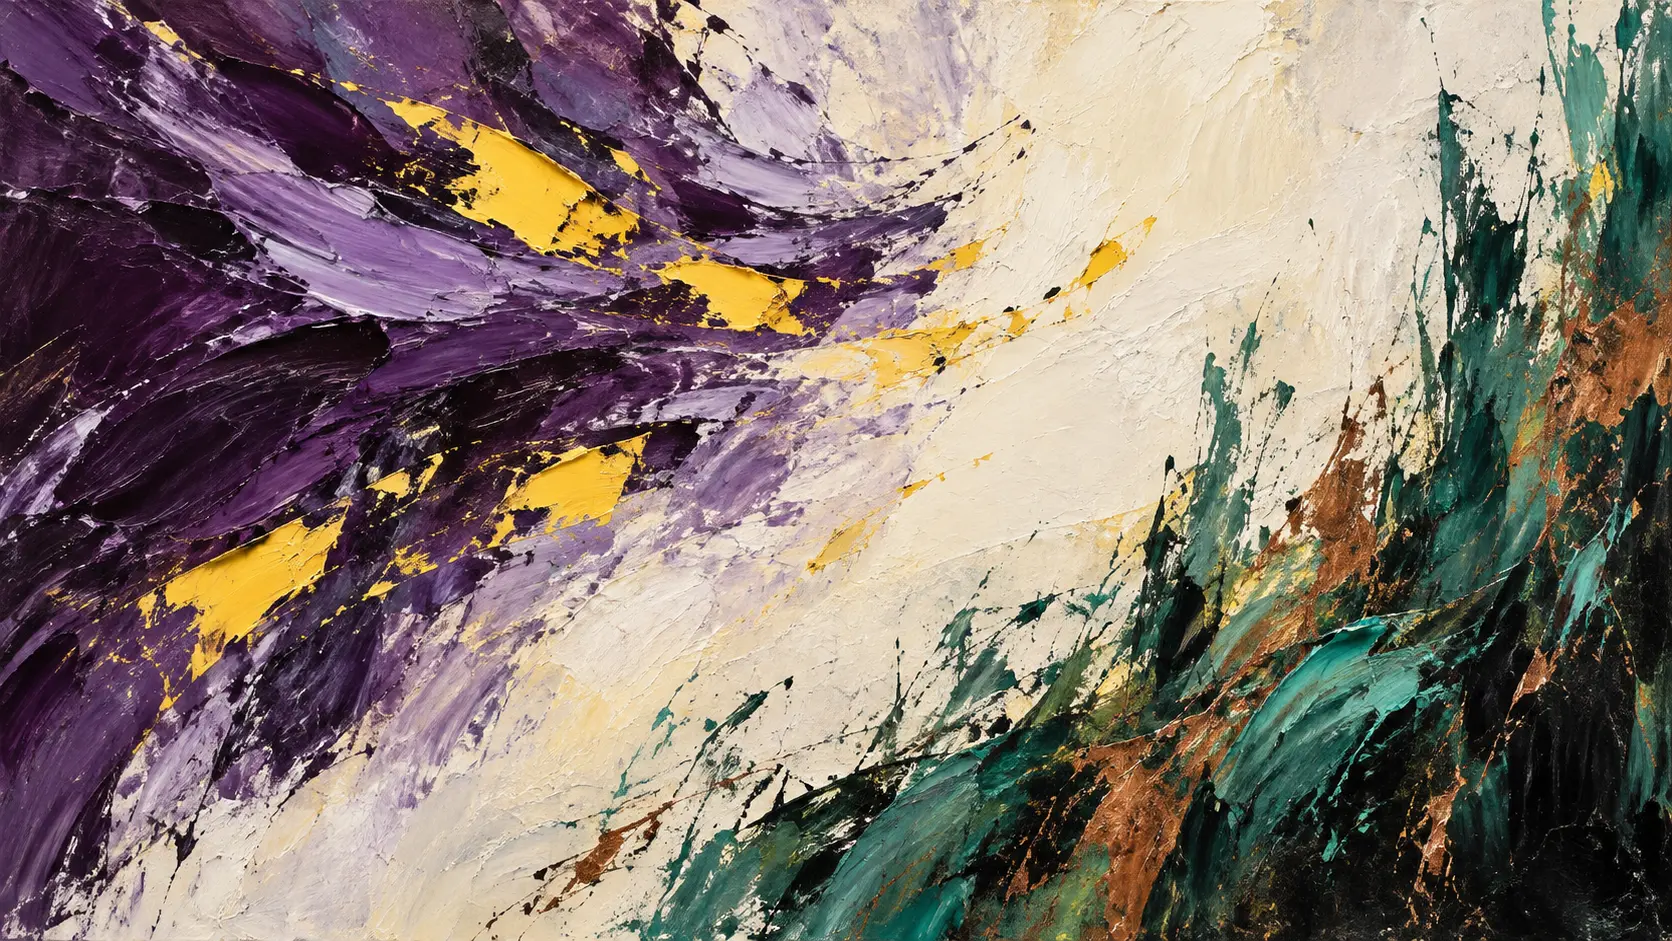
In the illustration, fast violet movement carries yellow fragments towards an open interval while green-black marks gather upward from below. Neither side becomes a wall or wins the canvas. The unresolved space is the institutional task: building enough independent capability to meet what is arriving without merely copying it.
Questions to carry forward
- Which frontier models must be provided for independent pre-release testing, and on what timetable?
- Can public evaluators test memory, tools and long-running agent behaviour rather than only the base model?
- How many of the 1,352 identified government vulnerabilities were independently validated and fully repaired?
- Who leads a serious cross-company agent incident, and what evidence can they compel or preserve?
- How will government separate its dependence on frontier AI suppliers from its duty to scrutinise them?
 Puzzle